APIs
The Knowledgator platform provides a suite of APIs and open-source models for information extraction and text understanding. Built on non-generative technologies, our models are up to 100x faster than LLMs and produce deterministic outputs by design — no hallucinations, no inconsistencies. Despite their compact size, they work zero-shot without requiring additional training. You can select ready-to-use models and industry-specific adapters, or fine-tune your own for additional performance — all from a single platform.
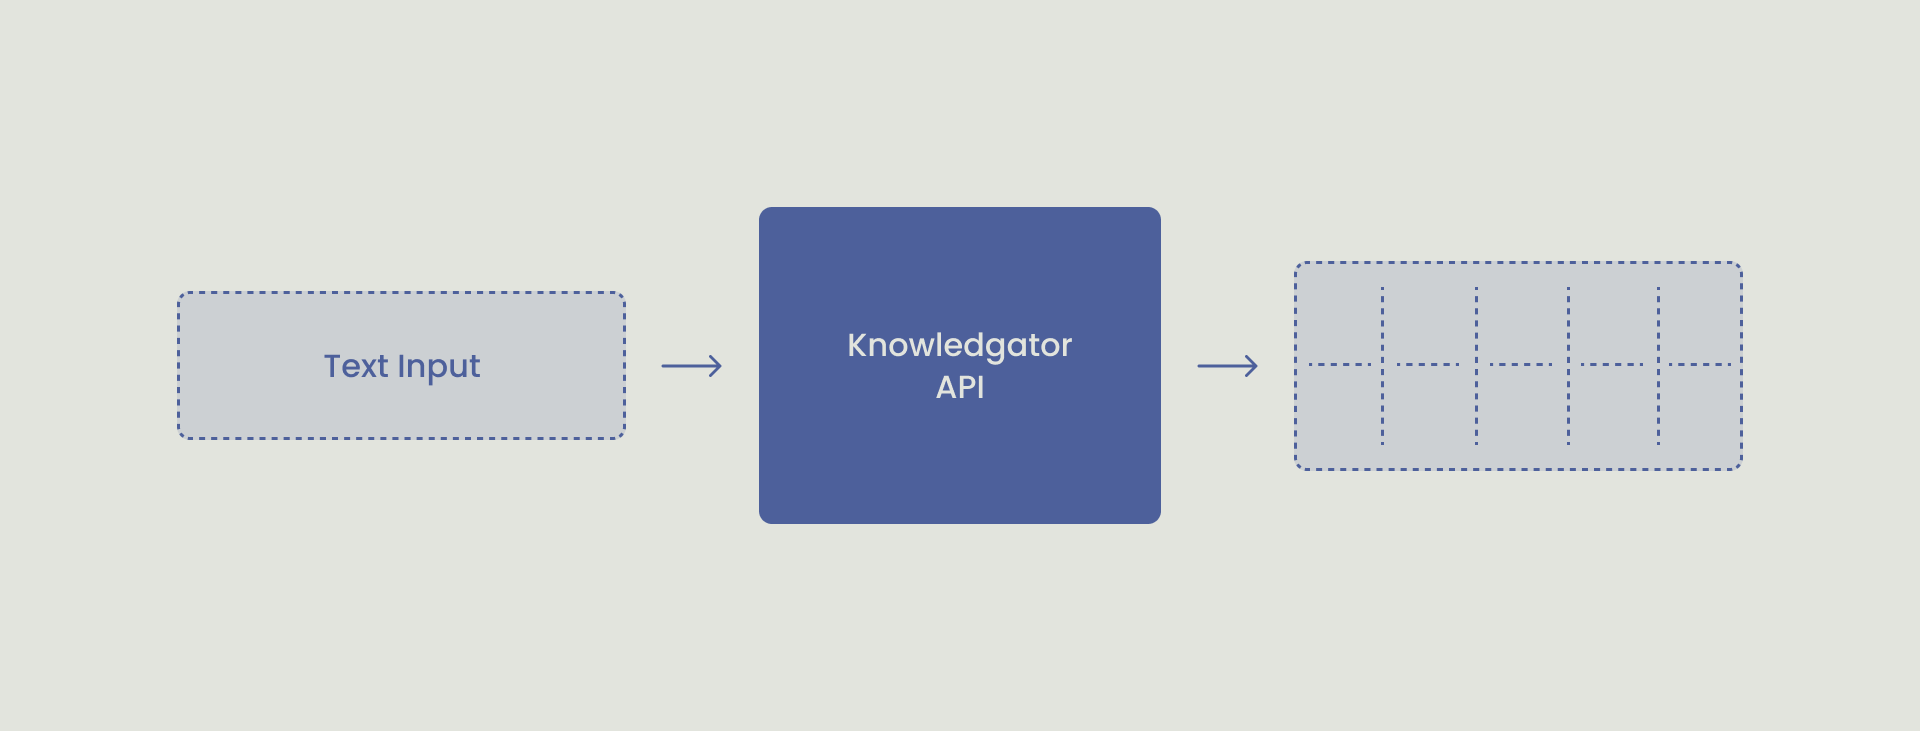
At their core, our APIs convert unstructured text into structured output based on the task and your instructions.
Getting Started
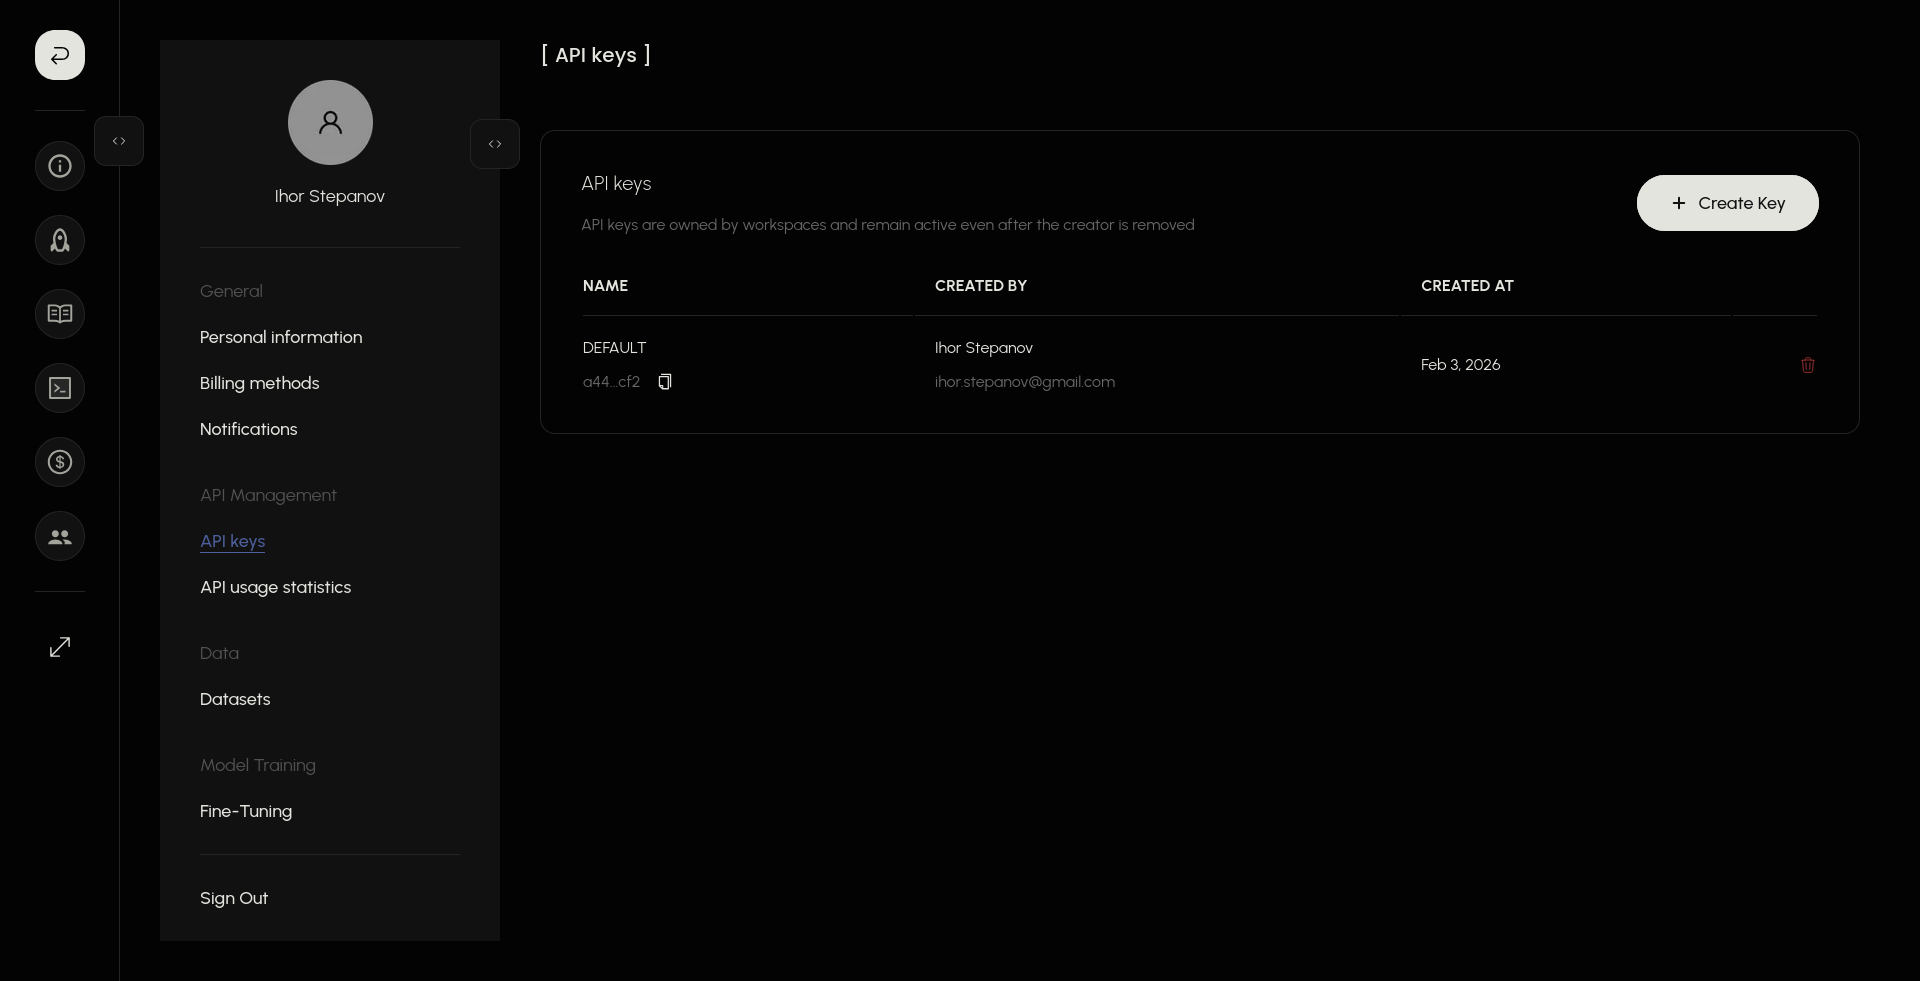
- Sign up or sign in on the Knowledgator platform.
- Generate an API key from your account settings.
- Explore the APIs interactively on the API reference page before integrating them into your application.
- Prefer using an official SDK? Explore the Python SDK or TypeScript SDK guides.
How Knowledgator Compares
| Feature | LLMs | Knowledgator | Traditional NLP |
|---|---|---|---|
| Speed | Slow (autoregressive generation) | Fast (up to 100x faster than LLMs) | Fast |
| Zero-shot capability | Yes | Yes | No (requires task-specific training) |
| Few-shot adaptation | Yes (via prompting) | Yes (via fine-tuning with a few examples) | No (requires large labeled datasets) |
| Output structure | Unstructured, requires parsing | Structured | Structured |
| Determinism | Non-deterministic | Deterministic by design | Deterministic |
| Hallucinations | Prone to hallucinations | No hallucinations | No hallucinations |
| Long-context support | Varies by model | Up to 150K tokens | Limited |
| Custom entity/relation types | Via prompting | Via zero-shot or fine-tuning | Requires retraining |
| Cost | High (large compute) | Low | Low |
| Integration | Complex (prompt engineering) | Simple REST API | Requires ML pipeline setup |
Available APIs
Comprehend-it
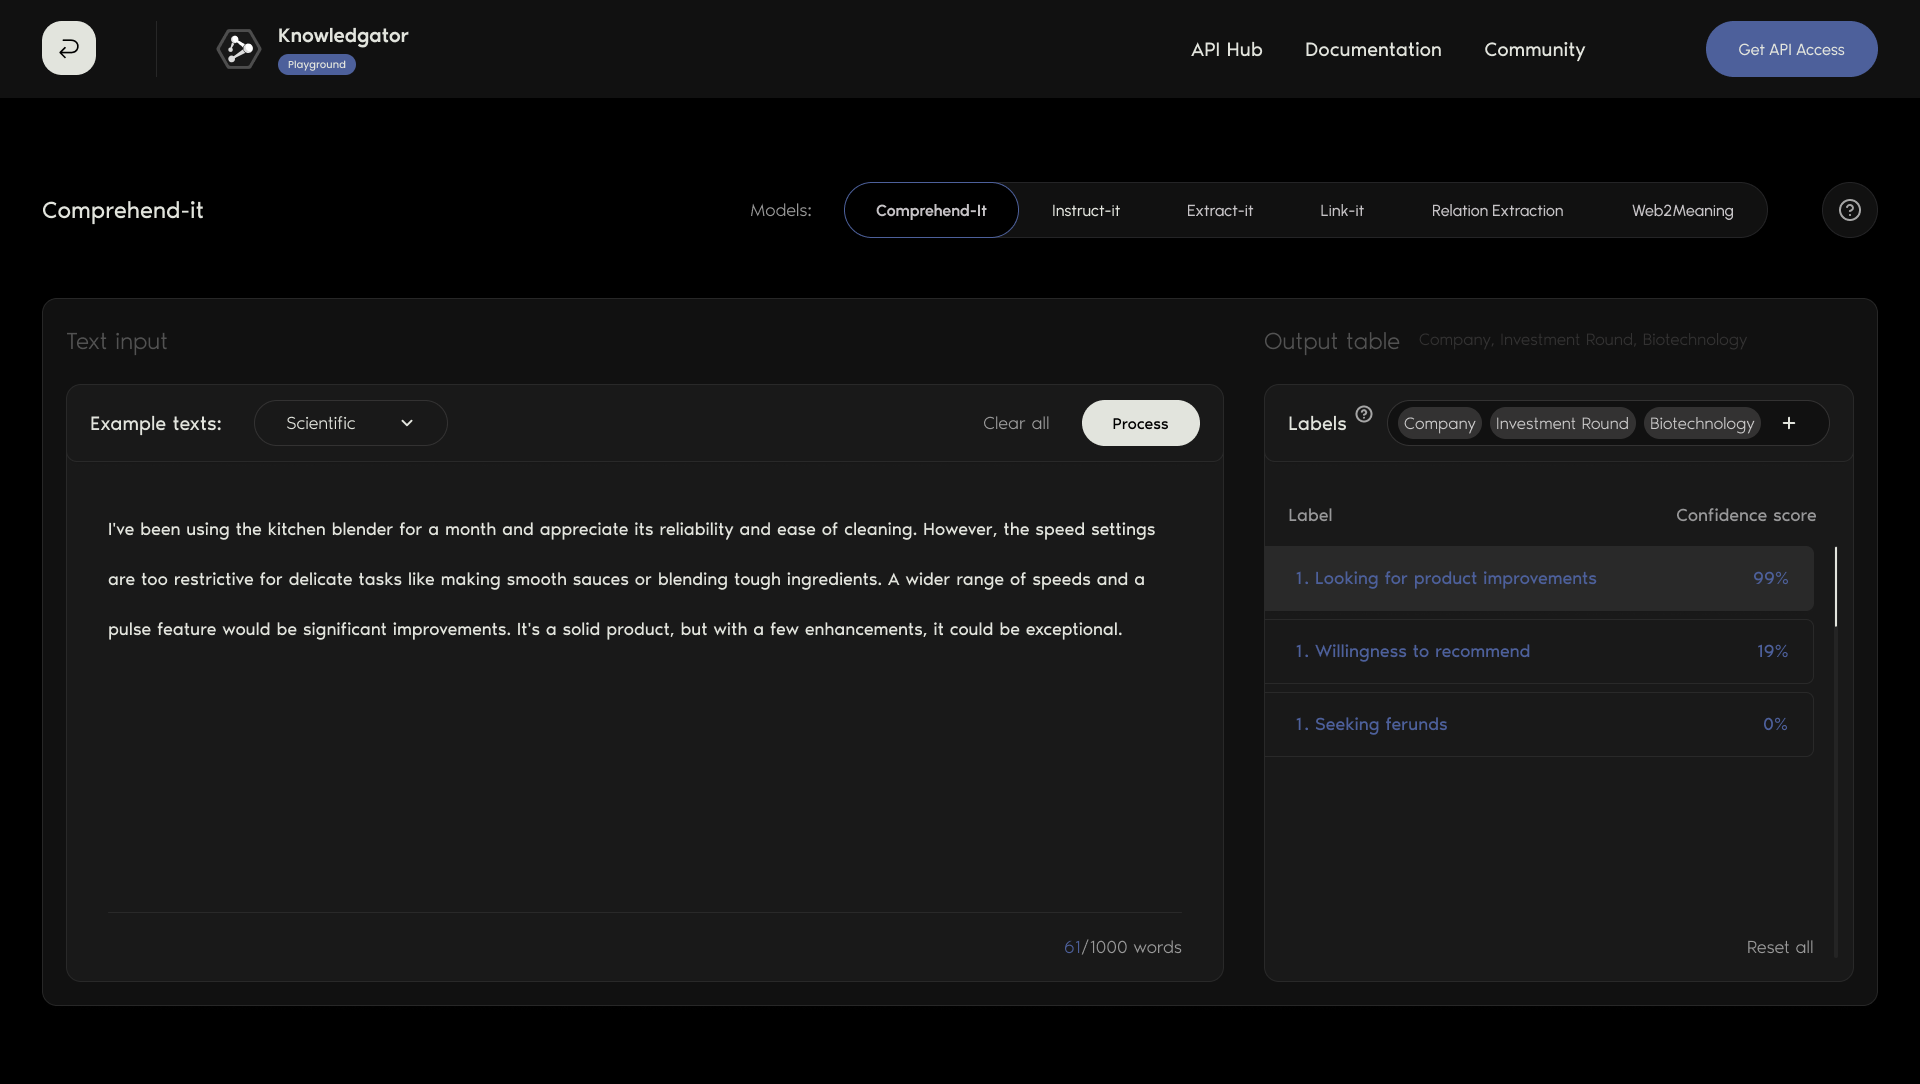
An efficient zero-shot and few-shot classifier for text categorization. Comprehend-it classifies text into arbitrary categories without prior training, supporting inputs of up to 150K tokens. It handles hierarchical labels, allowing you to encode complex taxonomies, and accepts an optional prompt to clarify how the classification should be performed.
Extract-it
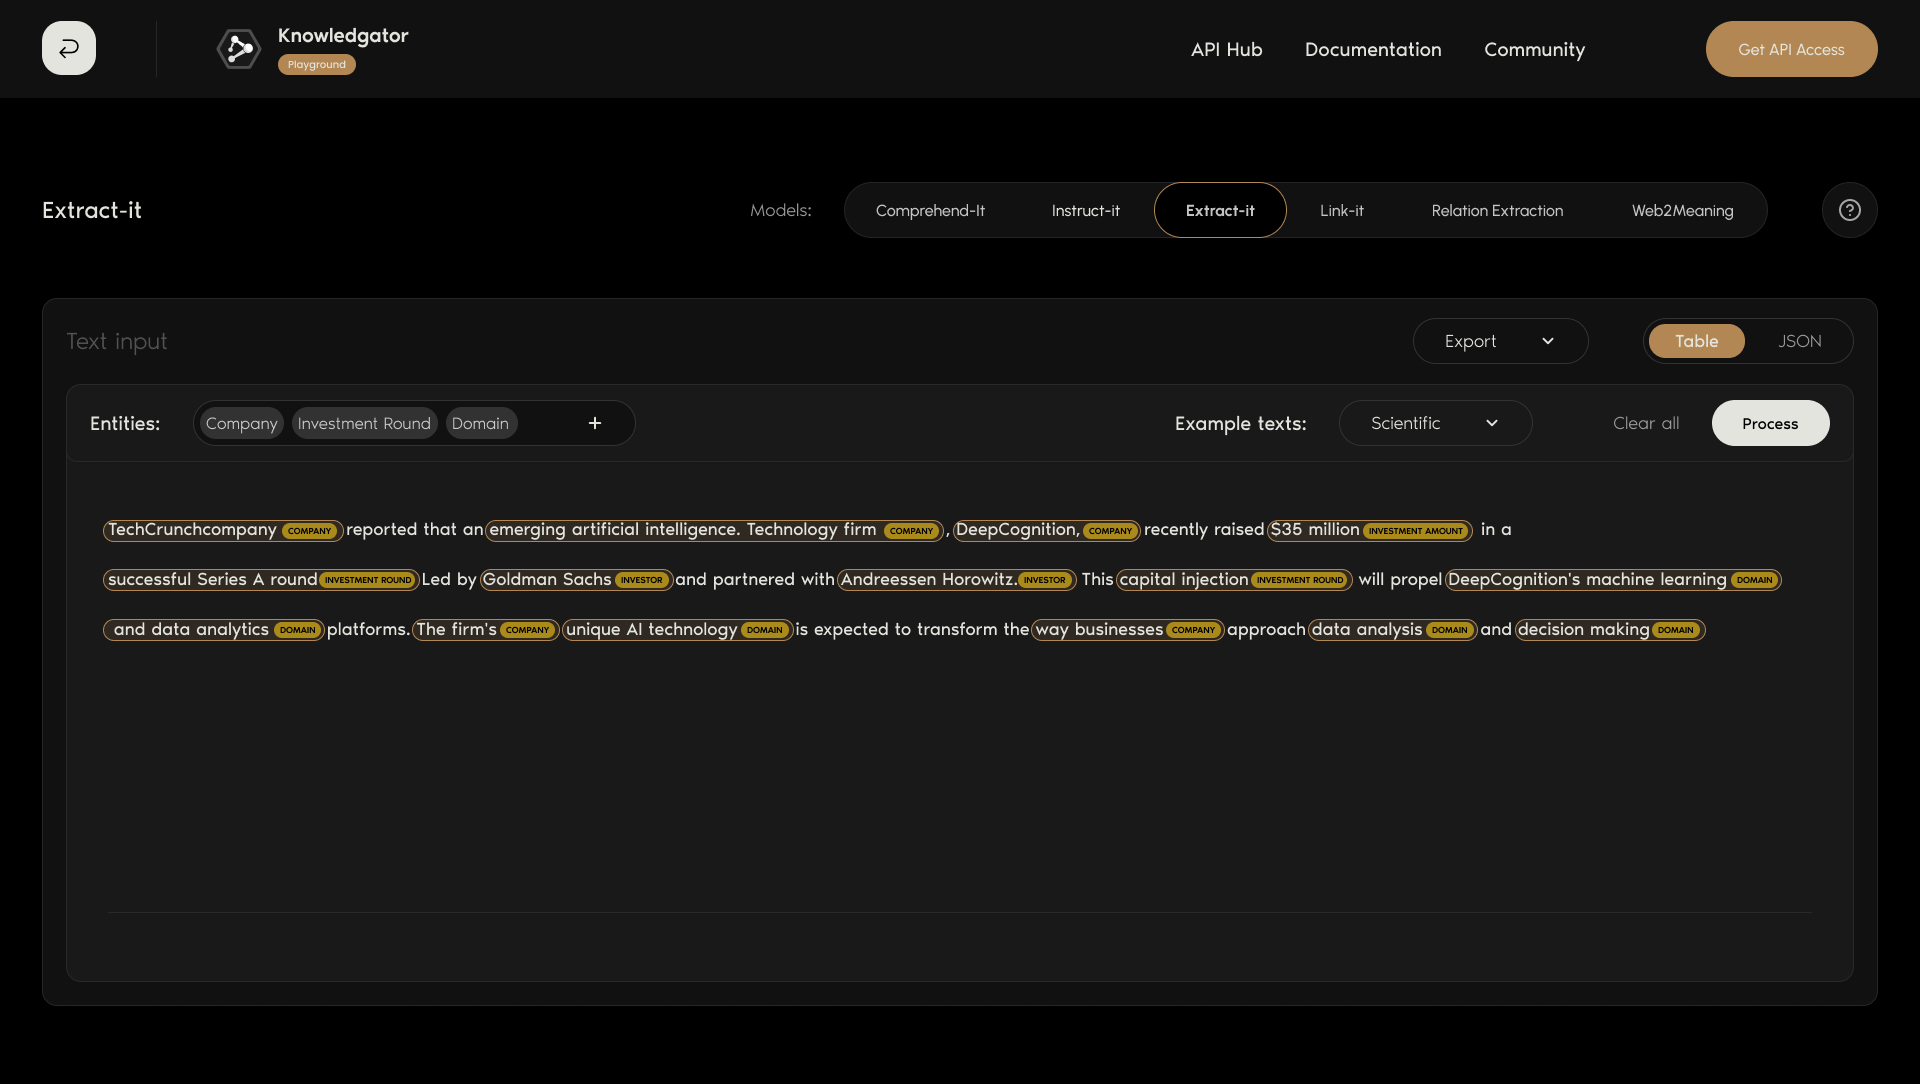
A fast information extraction API for NER, relation extraction, and summarization. Extract-it works zero-shot, letting you define custom entity types and relations on the fly. You can provide a prompt describing what information to extract. The API returns structured output with exact span positions and confidence scores.
Instruct-it
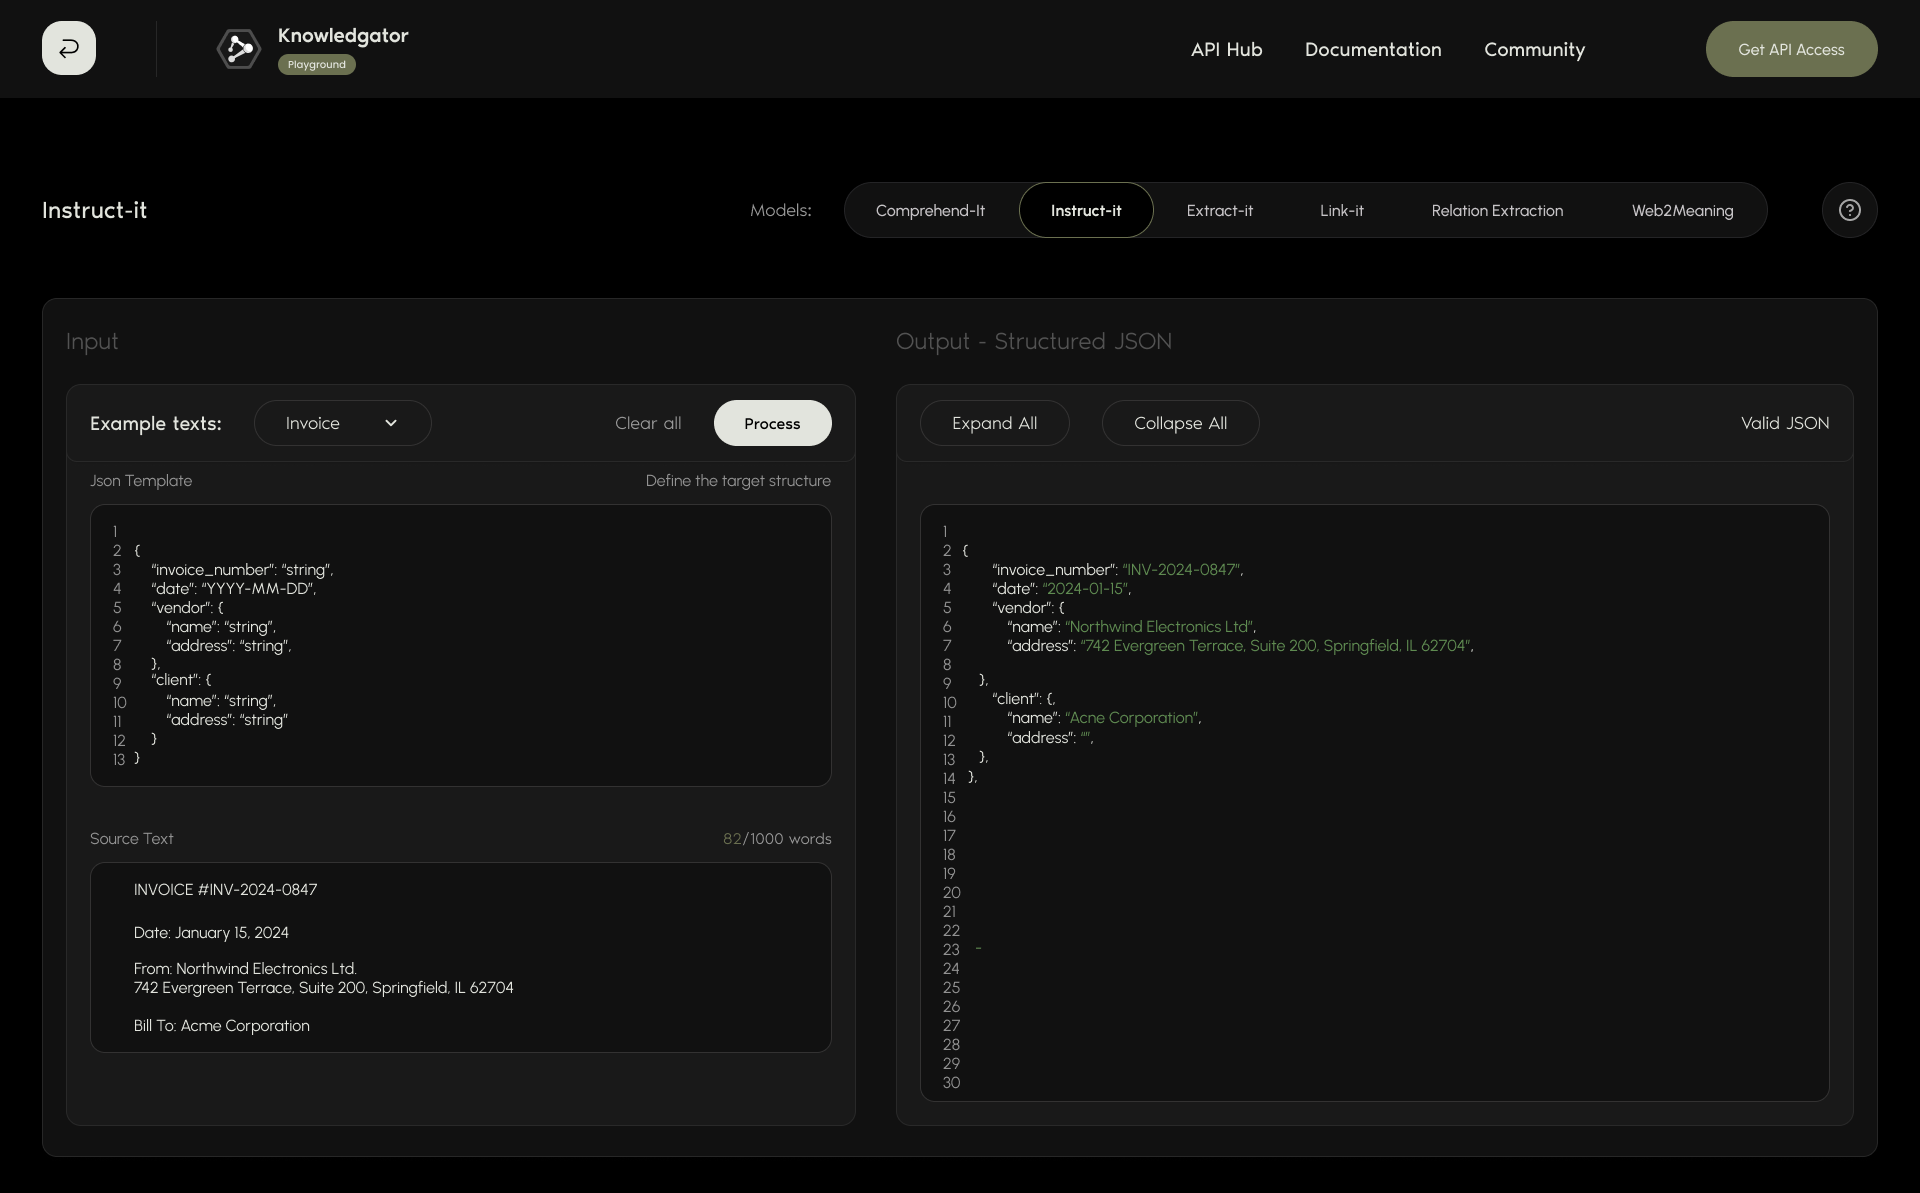
A multimodal instruction-based model for information extraction. Instruct-it accepts natural language instructions and produces structured outputs in JSON, XML, or Markdown format, making it versatile across a wide range of extraction tasks.
Link-it (Coming soon)
An entity linking API that connects extracted entities to your custom knowledge bases or databases. Link-it disambiguates mentions in text and maps them to the correct entries, enabling seamless integration with your existing data. Unlike traditional tools, Link-it works zero-shot and does not require retraining. You can upload and update custom entity catalogs at any time.
Supported Tasks
The platform covers a broad range of information extraction and text understanding tasks:
- Text Classification & Categorization — zero-shot and few-shot classification without task-specific training.
- Named Entity Recognition (NER) — extract entities from text with custom or predefined entity types.
- Relation Extraction — identify and label relationships between entities.
- Entity Linking & Disambiguation — map extracted entities to entries in custom knowledge bases.
- Sentiment Analysis — determine the sentiment polarity of text.
- Intent Recognition — classify user intents from text inputs.
- Question Answering — extract answers from provided contexts.
- Text Summarization — produce concise abstractive or extractive summaries of long documents.
- Open Information Extraction — extract structured triples from unstructured text.
- Structured Data Generation — convert unstructured text into JSON, XML, or Markdown.
- Web Scraping & Content Cleaning — extract and categorize content from web pages.
Platform Capabilities
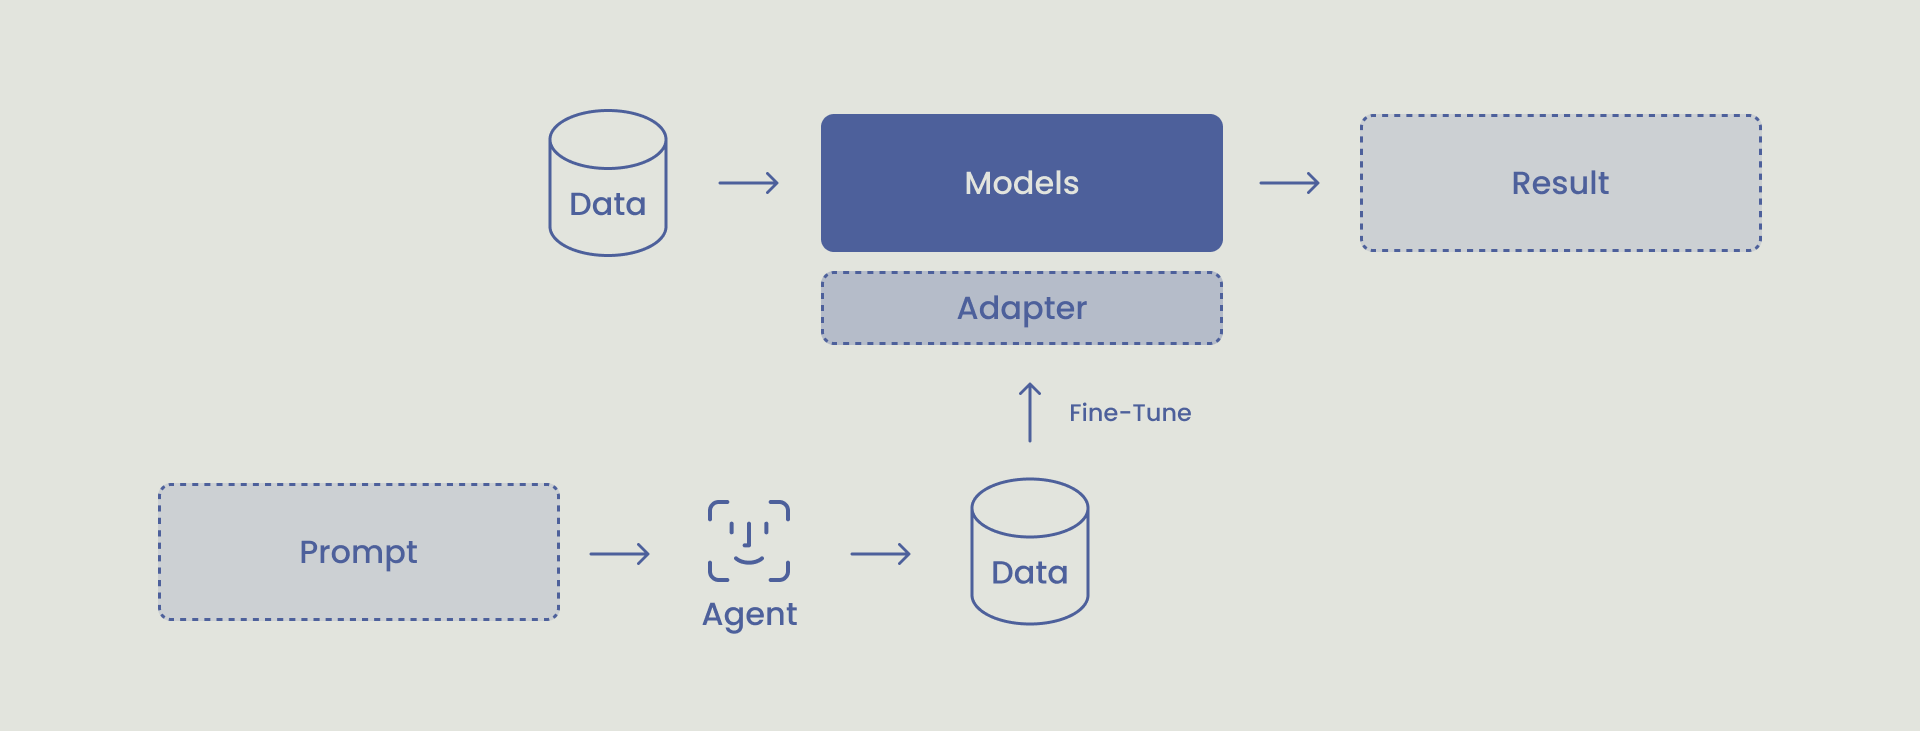
The platform supports the full lifecycle of building and deploying information extraction models — from synthetic data generation and fine-tuning to efficient inference. You can select the best model for your needs or export it for private use.
Inference
All APIs support zero-shot and few-shot inference, so you can get started without any training data. Models handle inputs of up to 150,000 tokens and return structured outputs with confidence scores. You can select any model that fits your needs, or apply existing and fine-tuned adapters.
Open-Source Model Deployment
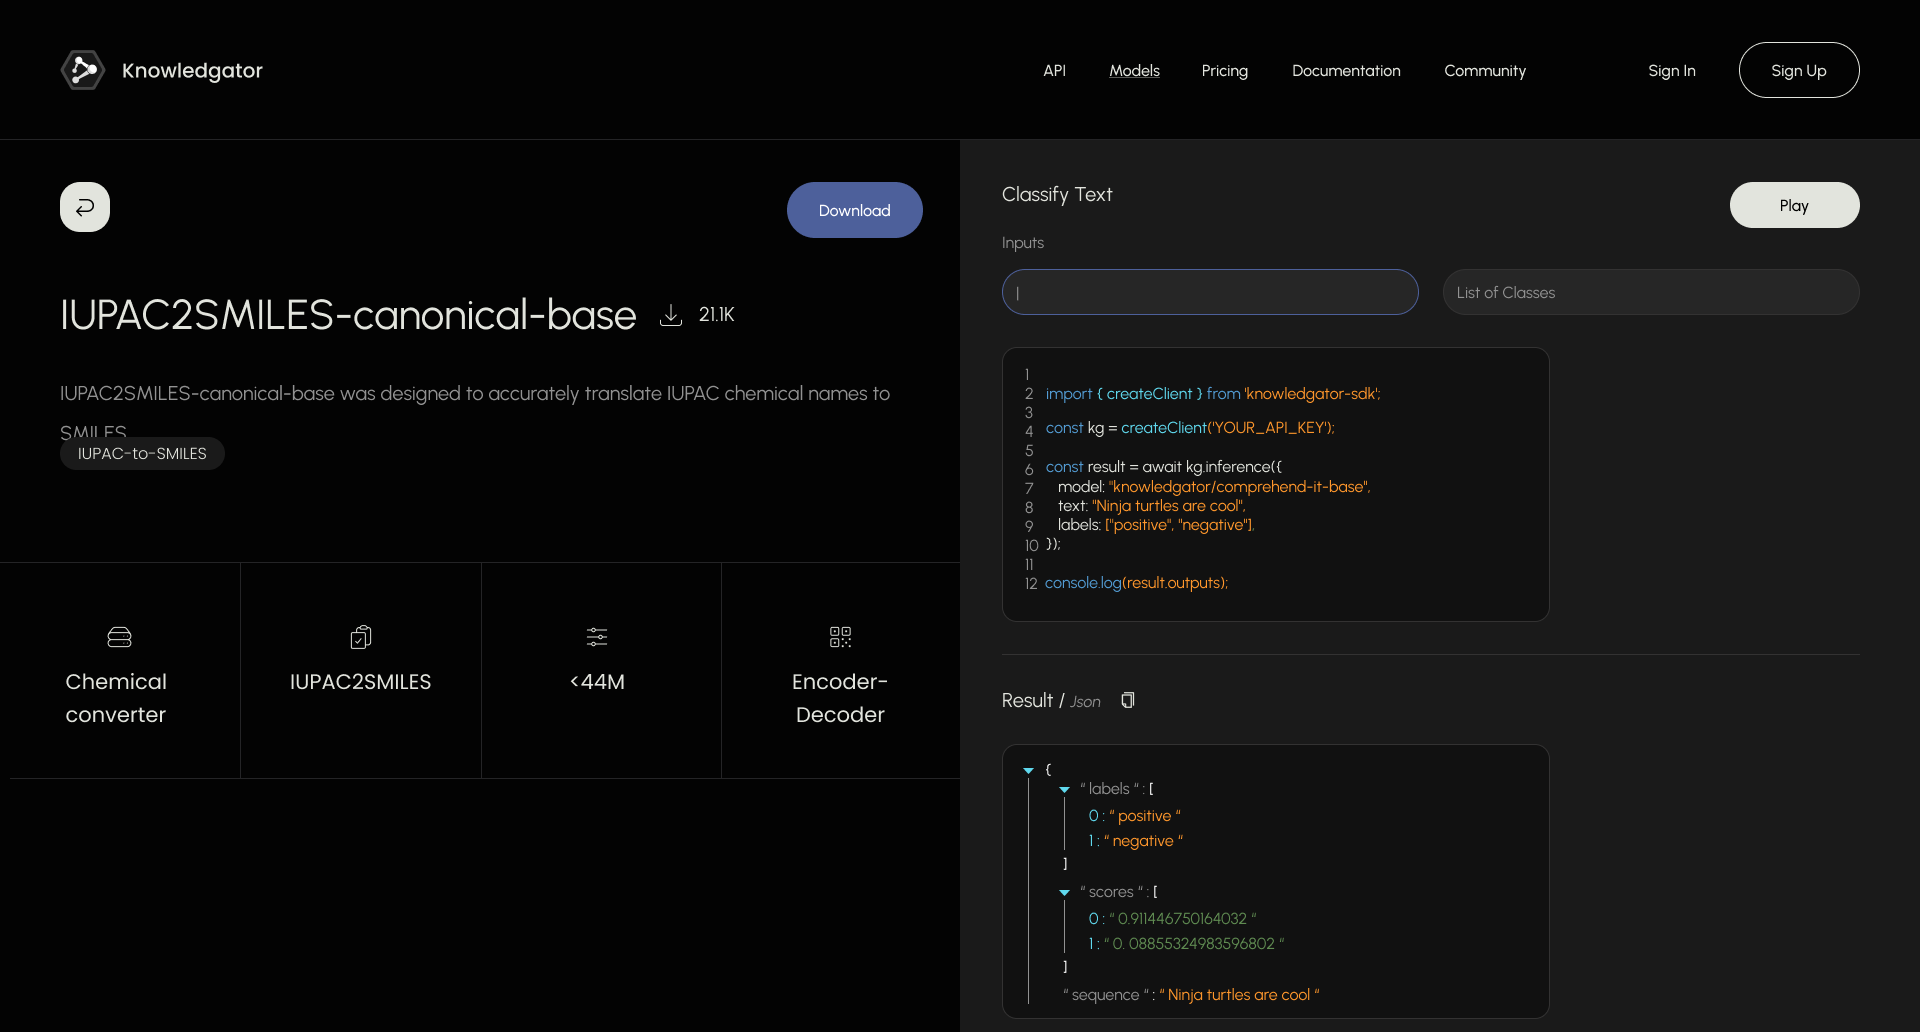 Deploy open-source models from the Knowledgator ecosystem through the platform — run and scale models without managing infrastructure. You can also export models to ONNX format for local development.
Training & Fine-Tuning
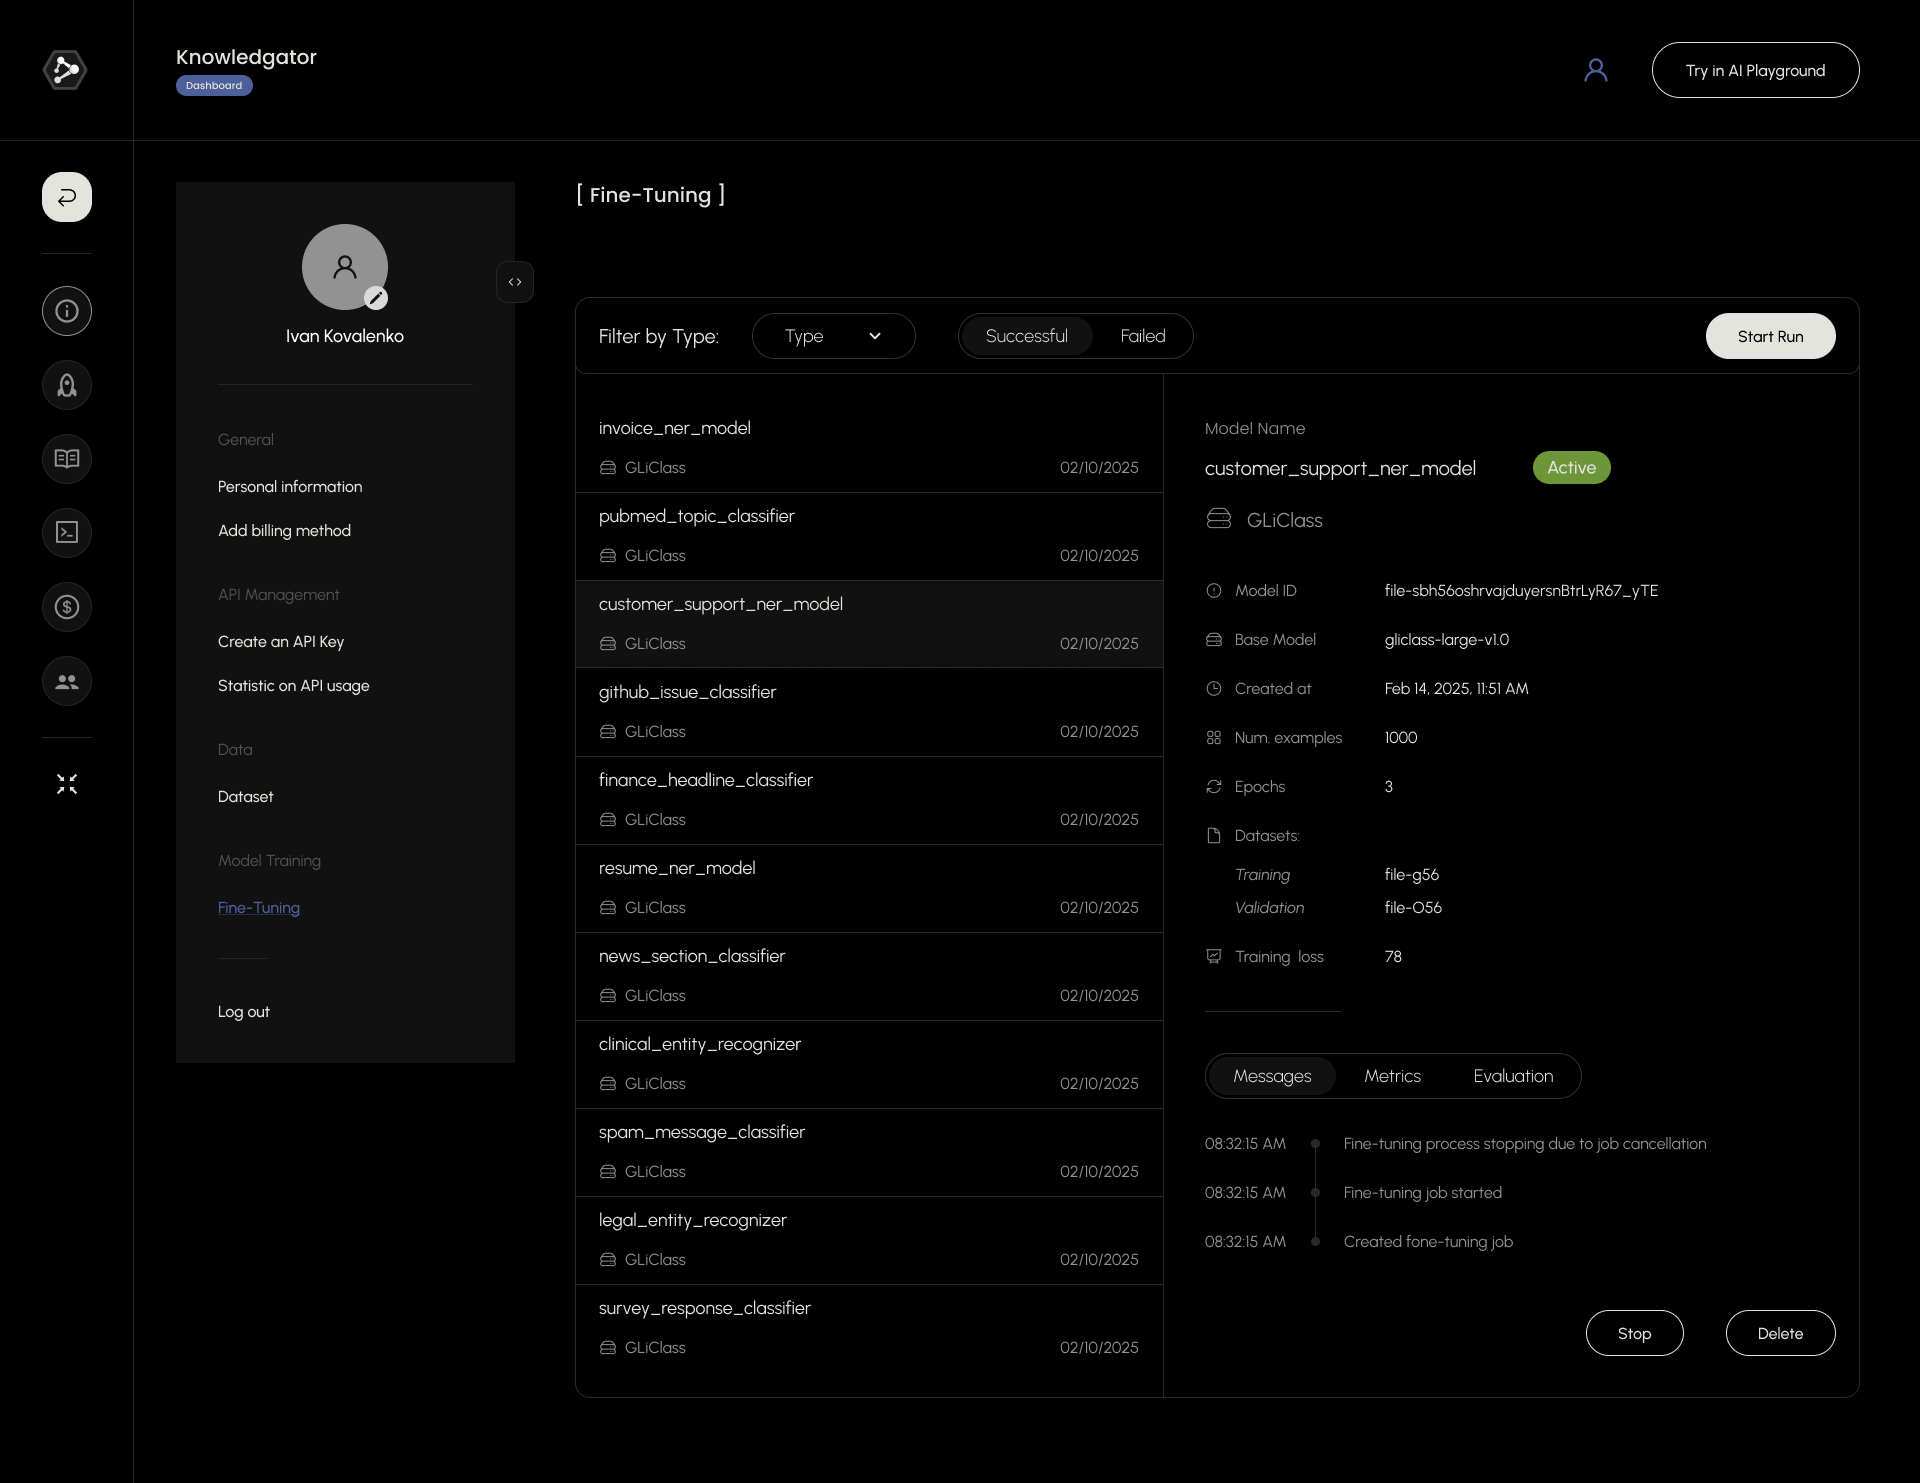 Fine-tune models with just a few examples to achieve results on par with fully supervised approaches. The platform provides configurable hyperparameters — batch size, learning rate, number of epochs — and lets you monitor training runs and iterate on experiments efficiently.
Dataset Management
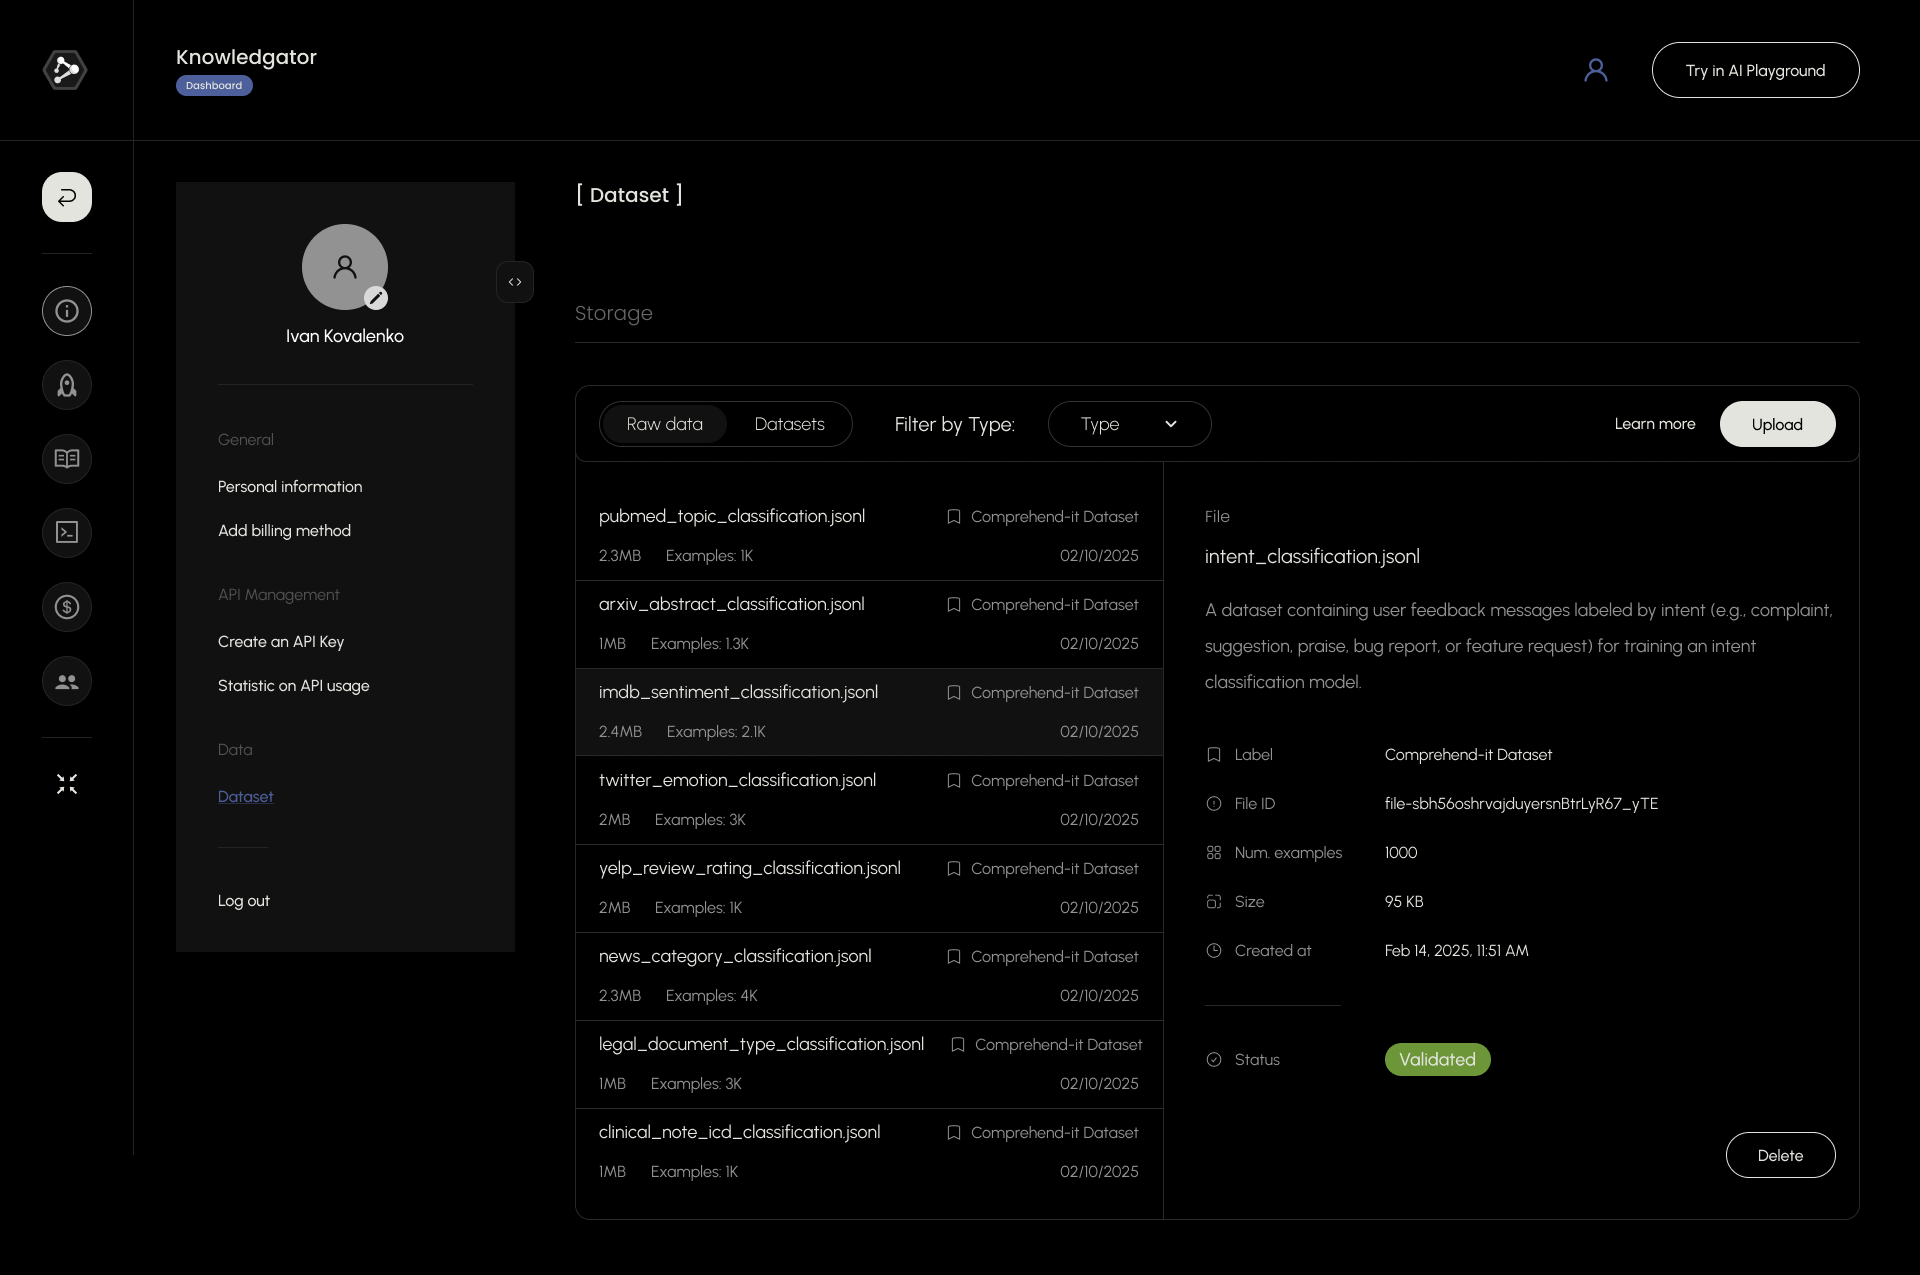 Upload and manage your own datasets directly on the platform, or generate synthetic data for training custom models. Datasets integrate seamlessly into the fine-tuning workflow for both training and validation, streamlining the path from data preparation to deployment. You can also download datasets for use in external projects.